 Your Cloud Audit Is Already Too Late
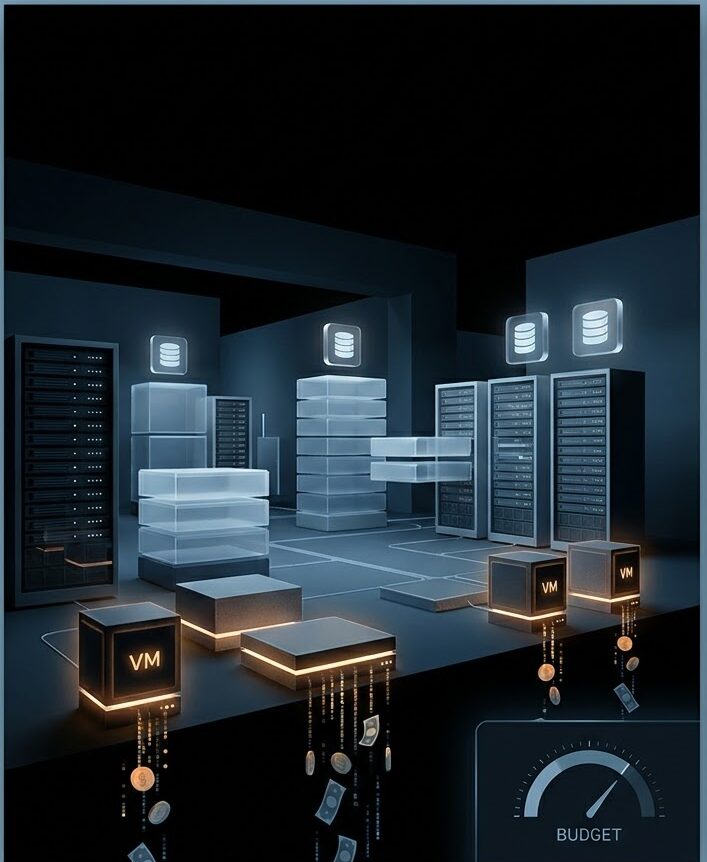
Most teams treat cloud cost audits like fire drills: they happen after smoke is already visible. By the time finance flags a spike, you’ve already paid for weeks of idle load balancers, orphaned volumes, and oversized instances running at 8% CPU. The bill is the trailing indicator. The waste happened in real time.
Waiting for a cloud bill to trigger waste remediation is tactical malpractice. The only defensible posture is continuous, application-aware detection that finds idle resources before they accrue charges, not after the finance team escalates. The difference between these approaches isn’t methodology—it’s timing. One costs you money. The other saves it.
Cloud waste is the share of provisioned capacity you’re billed for but never use: idle EC2 instances, unattached EBS volumes, abandoned snapshots, zombie Lambda functions, oversized Reserved Instances. According to the basic arithmetic of scheduled audits, if you run a monthly review, you pay for waste during the 29 days between scans. A quarterly audit leaves you exposed for 89 days. The gap is the expense.
The scheduled audit model is structurally late
Quarterly or monthly audits inherently miss waste because cloud resources idle between scans. You pay for that gap. A load balancer that spins up on Monday and serves zero traffic until your Thursday audit costs you three days of charges before anyone notices. Multiply that pattern across dozens of services and hundreds of resources, and the delay becomes expensive.
Scheduled audits miss waste because resources idle between scans, so continuous detection is the only way to keep waste off the next bill. The calendar doesn’t care about your audit schedule. Resources accrue charges every hour. Detection needs to run on the same clock.
A single cleanup pass, however thorough, degrades within a quarter. New waste appears constantly as teams ship infrastructure. A developer spins up a staging environment for a feature branch, merges the code, forgets to tear down the environment. That instance runs until the next scheduled audit. If your audit cycle is monthly, you pay for 30 days of waste that served a purpose for three.
The other problem with snapshot-based reviews is false positives. A resource that looks idle in a one-time check might serve traffic during a monthly batch job or a rare failover. You need validation over weeks, not a single moment. A load balancer with zero connections on the day you check might handle the monthly invoice run. An RDS instance with low CPU might support a quarterly reporting job. The only way to distinguish genuine waste from intermittent use is sustained observation.
Regular audits and reviews ensure that cloud resources are being used optimally and that any cloud waste is identified and addressed promptly, but “regular” is doing the heavy lifting in that sentence. If regular means quarterly, you’re guaranteeing 90 days of accumulated waste before remediation. If it means daily, you’re closer to real cost control.
Application behavior, not CPU thresholds, defines genuine waste
Threshold-based scripts that flag low CPU usage produce false positives because they lack business context. A database running at 5% CPU might be idle, or it might be a read replica waiting for failover. You can’t tell the difference by measuring processor load.
True waste detection reads application signals like invocation count, error rate, and traffic patterns over sustained periods. For Lambda, the detection signal is invocation count over a rolling 30-day window. Zero invocations for 30 days paired with zero errors is a strong idle signal because the function has no active purpose. It’s not waiting for a rare event. It’s not serving traffic you forgot to instrument. It’s dead code still accruing charges.
Detect waste by reading application behavior, not by scheduled CPU audits. An EC2 instance with low CPU might be running a memory-intensive caching layer. A NAT gateway with low throughput might be the only egress path for a critical microservice. CPU usage alone doesn’t tell you whether the resource has business value.
The distinction matters because autonomous elimination beats threshold scripts. Application behavior, not CPU averages, decides whether a resource is genuinely waste. A script that terminates anything below 10% CPU will eventually delete something important. A system that tracks zero invocations, zero errors, zero ingress traffic, and zero egress traffic over 30 days is making a diagnosis, not a guess.
Verify usage over weeks, not a single snapshot, before removing anything—a resource that looks idle today might serve a monthly batch job or rare failover. The validation window is the safety mechanism. If a resource shows zero use across every pattern you track for a sustained period, that’s a strong candidate for automated remediation. Anything with intermittent signals stays flagged for human review.
Start with the usual suspects, not exotic optimization
The majority of recoverable waste comes from a short list: unattached storage volumes, idle load balancers, unused NAT gateways, and oversized instances. Hunting for sophisticated inefficiencies before clearing the obvious is misallocated effort.
Most cloud waste comes from a short list of usual suspects: unattached storage volumes, idle load balancers, unused NAT gateways, and oversized instances running well below their allocated capacity. Start there before looking for anything more exotic. These resources account for the majority of easy-to-fix waste in most environments. You don’t need machine learning to find an EBS volume that’s been unattached for six months.
You can reduce waste almost immediately by zeroing in on resource waste: shutting down unused workloads after hours, rightsizing EC2 and RDS instances based on actual usage, replacing On-Demand instances with Spot or Reserved Instances. The low-hanging fruit isn’t hidden. It’s sitting in your console, accumulating charges while you plan a more sophisticated optimization strategy.
Dev, staging, and test environments running 24/7 when they’re only used during working hours are one of the most common and consistent sources of waste. A staging cluster that runs around the clock but only serves traffic between 9 AM and 5 PM on weekdays is wasting 71% of its runtime. Schedule-based shutdown outside business hours is the difference between a one-time fix and a sustained one.
The temptation is to chase complex optimizations—tuning autoscaling policies, rewriting applications to use cheaper storage tiers, rearchitecting for serverless. Those projects have value, but they take weeks. Deleting an unattached volume takes seconds. The ROI on the obvious stuff is immediate.
Beyond removing unused resources entirely, look at instances running well under their provisioned capacity. Rightsizing based on actual usage over time, not the original provisioning decision, typically finds savings well after the first pass of obvious waste has been cleared. The instance that made sense in 2022 when you were scaling aggressively might be three sizes too large today.
Hourly granularity and team-specific alerts prevent lag
Day-level granularity omits anomalies that happened within a particular window. If a misconfigured autoscaling group spins up 50 instances at 2 AM and terminates them at 6 AM, daily aggregation hides the spike. You need hourly visibility to trace waste to the commit or deployment that caused it.
Your cost management platform should pinpoint the exact hours of the anomaly. Day-level granularity is forensically useless. You can see that Thursday was expensive, but you can’t see that the cost spike happened between 14:00 and 16:00 UTC, which maps to the deployment window for the new feature release. Hourly granularity gives you the diagnostic signal needed to connect cost anomalies to engineering events.
Alerts should go only to the teams or engineers responsible for the affected infrastructure, not broadcast widely. A Slack channel that posts every cost anomaly to #engineering creates alert fatigue and diffuses responsibility. Nobody owns the problem because everybody was notified. Team-specific alerting routes the signal to the person who can actually remediate it.
Set up automated ways to detect, track, and report abnormal cloud activities before they affect costs, rather than relying on manual checks. Automation doesn’t mean autonomous deletion. It means detection happens continuously, alerts reach the right people immediately, and the feedback loop closes before the waste compounds.
The difference between reactive and proactive cost management is lead time. Reactive teams find out about waste when finance sends an email. Proactive teams get an alert the hour the waste starts accruing and remediate it before it reaches the bill.
Automate only what’s genuinely low-risk, keep humans in the loop elsewhere
Autonomous elimination of resources with zero use across every tracked pattern for sustained periods is safe. A Lambda function with zero invocations, zero errors, zero network activity, and zero logs for 60 days isn’t coming back. You can delete it without human confirmation.
Once a resource has shown zero use across every pattern you track for a sustained period, that’s a strong candidate for automated remediation. The key phrase is “every pattern.” If any metric—invocation count, error rate, ingress traffic, egress traffic, active connections—shows non-zero values during the observation window, the resource stays flagged for review. Automation proceeds only when the evidence is unambiguous.
Everything else—resources with intermittent traffic, failover roles, or batch schedules—requires human confirmation before termination. A database replica with low but non-zero replication lag might be your disaster recovery failover target. An instance with traffic spikes on the first of every month might be running payroll. These resources need context that automated systems can’t infer from metrics alone.
Schedule-based shutdown for non-production environments outside business hours is the difference between a one-time fix and a sustained one. This is the safest form of automation because the risk is scoped: dev and staging environments don’t serve production traffic, and the shutdown schedule aligns with known usage patterns. If someone needs the environment outside normal hours, they can override the schedule. The default state is off, not on.
Autonomous elimination beats threshold scripts because application behavior, not CPU averages, decides whether a resource is genuinely waste. A threshold script flags anything below 15% CPU and hopes you’ll review the list. An application-aware system tracks Lambda invocations, API gateway requests, database queries, load balancer connections, and storage I/O, then flags resources with zero activity across all dimensions. One approach generates false positives. The other generates actionable recommendations.
## Track savings against actual billing outcomes, not scan estimates
A waste-detection scan gives you an estimate. The number that matters is what shows up on the actual bill after remediation. Many teams celebrate projected savings that never materialize because the estimate missed Reserved Instance coverage or commitment discounts.
Track savings against actual billing outcomes, not the initial scan estimate—the two numbers are often different, and only one of them is real. A scan might identify $50,000 in monthly waste, but if $30,000 of that is covered by Reserved Instances you’ve already paid for, the actual cash savings is $20,000. The estimate doesn’t account for the sunk cost of commitments.
The waste-detection scan gives you the gross number. The bill tells you the net impact. The difference is reserved capacity, savings plans, committed use discounts, and edge cases where deleting a resource doesn’t reduce the bill because the capacity was already purchased. Your cloud cost optimization platform should track all the savings you’ve realized centrally, not just projections.
This discipline also exposes remediation failures. If you deleted 100 idle instances and the bill dropped by half as much as projected, something didn’t work. Maybe the instances were covered by a Reserved Instance plan. Maybe they were part of an autoscaling group that immediately replaced them. Maybe the deletion succeeded but the storage volumes remained attached. The bill is ground truth. The scan is a hypothesis.
Measuring success against verified billing outcomes also creates accountability. It’s easy to generate a report listing thousands of dollars in potential savings. It’s harder to produce the actual cost reduction. Tracking realized savings separates the teams doing real optimization work from the teams generating spreadsheets.
Cost allocation without tagging: trace spend to code, not metadata
Tagging strategies fail because engineers forget, deployment pipelines skip enforcement, and legacy resources remain untagged. You can write policies that deny resource creation without mandatory tags, but those policies create friction, and friction creates exceptions, and exceptions create untagged resources.
Complete cost allocation means tracing every penny of your cloud spend to the appropriate sources or dimensions, whether customers, products, features, microservices, or teams. Tagging is one path. Code-driven allocation is another. The latter doesn’t require metadata discipline.
Tagging resources by environment, team, or workload provides clarity, but enforcement requires proactive governance like service control policies to deny provisioning resources without mandatory tags. Even with enforcement, you end up with legacy resources predating the policy, resources created through backdoors like manual console access, and resources provisioned by third-party tools that don’t honor your tagging schema.
The alternative is to trace spend directly to services, features, and teams based on infrastructure-as-code mappings, API calls, or service ownership records. If your Kubernetes namespace maps to a team, you don’t need to tag every pod. If your Lambda functions follow a naming convention that encodes the owning service, you don’t need tags. The metadata already exists in the resource structure.
This approach trades tagging for code-driven allocation to avoid metadata maintenance burden. You still get cost attribution. You just derive it from the deployment artifact rather than relying on engineers to remember to add a tag during incident response at 2 AM.
Counterargument: automation introduces unacceptable risk
Continuous detection and automated remediation introduce risk: a bot might terminate a resource that appears idle but actually serves a critical, infrequent function like monthly invoicing, quarterly reports, or disaster recovery failover. The objection is not hypothetical. It has happened, and it will happen again if you implement automation without safeguards.
This objection is valid only when detection ignores application context. The solution is not to abandon automation but to require sustained zero-use signals across every tracked pattern—invocation count, error rate, network traffic—over weeks, not hours. A Lambda function that handles quarterly tax filings will show invocations every 90 days. A 30-day observation window catches that pattern. A failover database will show non-zero replication lag, even if it never serves client traffic. The metrics distinguish “rarely used” from “actually idle.”
Resources with any activity, however rare, stay flagged for human review. Automation proceeds only when every dimension—compute, network, storage, application-level metrics—reads zero for the entire observation window. If a single API call, a single database query, a single byte of egress traffic occurs during that period, the resource is excluded from automated remediation and routed to the review queue.
The alternative, reactive auditing after the bill arrives, guarantees you pay for waste. You’re choosing between two risks: the risk of over-automation, which is manageable with proper validation windows, and the risk of under-automation, which is a certainty. One risk you can engineer around. The other you’re signing a check for every month.
The cost of a false positive—deleting a resource that shouldn’t have been deleted—is a restoration from backup and an incident retro. The cost of a false negative—keeping a resource that should have been deleted—is thousands of dollars per month compounding over time. The magnitudes are not symmetric. Over-caution is more expensive than occasional errors, because you pay for over-caution every billing cycle.
Cloud waste reduction is a timing problem, not a methodology problem. The teams that win are the ones who detect waste before it accrues charges, automate remediation where risk is genuinely low, and measure success against the actual bill, not the scan estimate. Everything else is just expensive procrastination.
The scheduled audit model is structurally late because resources idle between scans, and you pay for that gap. Application-aware detection solves the false positive problem that threshold-based scripts create. Starting with the usual suspects—unattached volumes, idle load balancers, oversized instances—delivers immediate ROI without complex optimization projects. Hourly granularity and team-specific alerts close the feedback loop before waste compounds. Automation works when it’s scoped to resources with sustained zero-use signals across every tracked dimension. And tracking savings against the actual bill, not the projection, separates real optimization from optimistic spreadsheets.
The alternative is to keep auditing after the money is gone, hoping that next quarter’s cleanup will stick. It won’t. New waste appears constantly. The only sustainable posture is continuous detection, selective automation, and measurement against the number that actually matters: the bill.