 Your 5% GPU Utilization Isn’t a Problem It’s a Clue You’re Using the Wrong Playbook
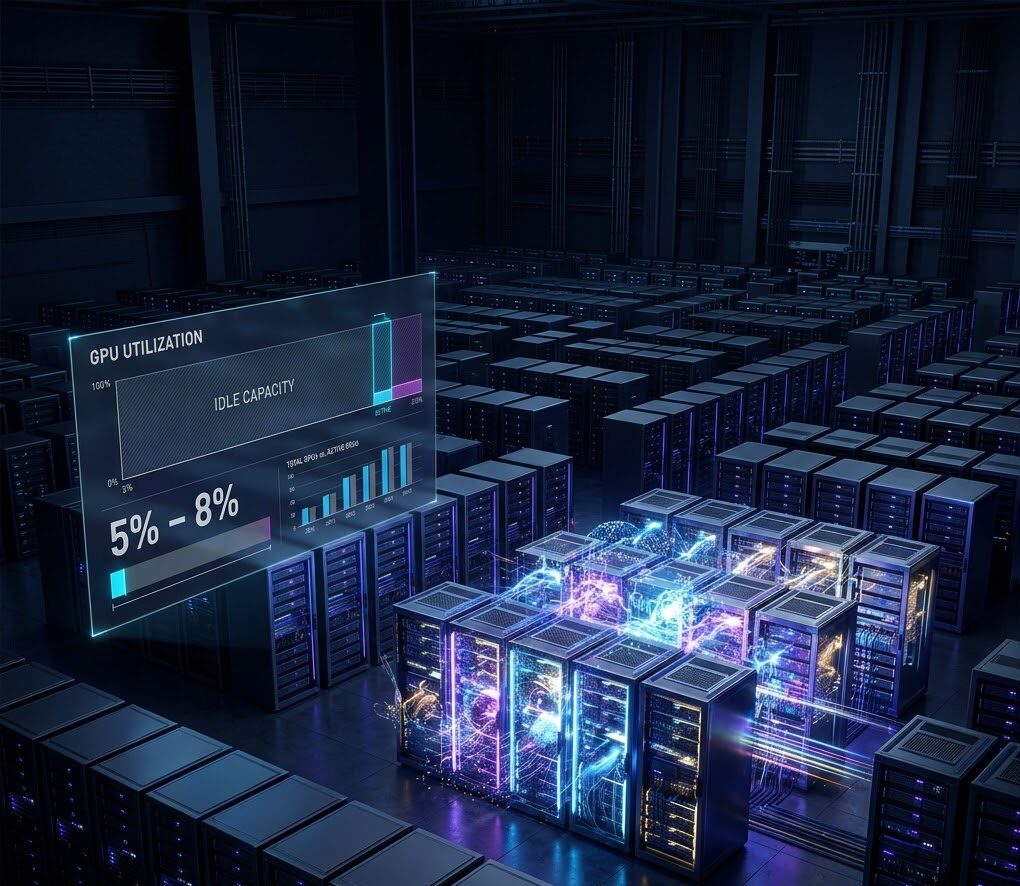
Your finance team wants chargeback. Your engineers want faster GPUs. Your GPU utilization dashboard shows 5-8%. All three problems have the same root cause: you’re applying steady-state FinOps rules to a workload pattern that resets its economics every time someone types ‘train new model.’
Traditional FinOps models built on steady-state compute and predictable utilization collapse under AI workloads because GPU demand oscillates between zero and peak within minutes, average utilization hovers at 5-8%, and every new model deployment resets the cost baseline—requiring a shift from allocation-based accounting to waste-elimination and per-workload unit economics.
The 5% utilization crisis isn’t a measurement problem it’s the workload
Industry-wide GPU utilization sits at approximately 5%, according to recent infrastructure surveys. Finance sees that number and assumes engineering incompetence. Engineering sees it and shrugs. Both reactions miss the structural truth: AI workloads are bimodal by nature, and the metric itself was designed for a different kind of computing.
Training jobs run at 100% utilization during convergence runs, then drop to zero between experiments. Inference loads spike to capacity during request bursts, then idle waiting for the next API call. Development environments sit provisioned ‘just in case’ because the 2024-25 GPU scarcity taught teams that waiting for capacity approval means missing quarterly objectives.
The problem compounds when organizations set aspirational targets—60% for training, 50% for inference—without acknowledging these are aspirations, not industry reality. Any GPU instance below 30% utilization technically qualifies as a right-sizing candidate, yet most organizations lack the telemetry to identify these instances in real-time, let alone explain *why* they’re idle.
FOMO reservations made during peak scarcity left organizations paying for on-demand capacity that now sits unused between workloads. The GPU is available, reserved, and bleeding cash while teams wait for the next training run. Traditional FinOps dashboards flag this as waste. AI teams call it necessary slack. Neither side has the tooling to prove their case with data.
The 5% number isn’t evidence of lazy teams. It’s evidence that your workload pattern doesn’t match your measurement framework.
Every model deployment resets your baseline traditional allocation fails
FinOps models designed for steady-state VM fleets assume next month looks like last month with 10-15% variance. AI invalidates this assumption every sprint. Each new training run, model version, or inference endpoint introduces novel cost patterns with no historical reference.
Training run cost is straightforward in theory: GPU count × hours to convergence × GPU hourly rate. But convergence time for new model architectures has no historical baseline until the first run completes. Your last training job took 48 hours on 16 A100s. This one? Could be 72 hours, could be 36. You won’t know until it finishes.
Traditional allocation formulas break instantly. The standard approach—`team_cost = (namespace_gpu_seconds / total_gpu_seconds) × cluster_monthly_cost`—assumes both numerator and denominator are stable or growing predictably. In AI environments, both change every sprint as teams launch new experiments, retire old models, and shift infrastructure between training and inference.
Organizations set annual GPU budgets based on historical patterns, but AI workload growth comes from new use cases, not linear scaling of existing ones. Last quarter you ran sentiment analysis on customer reviews. This quarter you’re adding document summarization, code generation, and conversational search. Each new model brings its own cost profile with zero historical data.
Per-token costs for inference vary by model size and quantization strategy. Switching from one model to another mid-quarter can change unit economics by 10× overnight. Your finance system expects smooth curves. AI gives you step functions.
The baseline resets with every deployment. Any allocation model that treats this month’s spend as a predictor for next month’s will be wrong before the invoice closes.
Chargeback requires stable unit economics, but GPU workloads have four conflicting cost models
Finance teams demand a single source of truth for chargeback. GPU workloads demand four simultaneous allocation models, and most organizations need at least two running in parallel.
Complete GPU chargeback requires tracking per-namespace allocation for Kubernetes teams, per-tenant usage for multi-tenant inference, per-token billing for API consumers, and per-experiment attribution for training jobs. Each model uses different denominators. Per-namespace splits by pod seconds. Per-tenant tracks API requests. Per-token counts tokens generated. Per-experiment attributes the full cost of a training run to a single team.
Traditional FinOps tooling maps one resource to one cost center. GPU clusters require splitting a single A100 across multiple teams, projects, and billing entities simultaneously via NVIDIA MIG partitioning, which can create up to 7 isolated instances per physical GPU. Your chargeback formula needs to handle fractional attribution where Team A consumed 3/7 of GPU-0 for inference while Team B used 4/7 for fine-tuning.
The technology stack for complete visibility requires DCGM Exporter for GPU metrics, Prometheus for time-series storage with team and project labels, Grafana for visualization, and optionally OpenCost or Kubecost for Kubernetes cost allocation. But none of this produces chargeback-ready numbers without custom formulas that join GPU seconds with hourly rates across multiple dimensions.
Showback reports must run for 4-6 weeks to build trust in multi-dimensional allocation before teams will accept formal chargeback integrated with finance cost center codes. Rush to chargeback without showback and teams will dispute every line item, surfacing tagging gaps and attribution bugs that should have been caught during the trust-building phase.
The complexity isn’t optional. It’s structural to how GPU workloads actually run.
Spot instances save 70-90% but break the utilization metric everyone tracks
Spot instances with checkpointing deliver 60-90% savings on training workloads and represent the highest-impact optimization available. AWS offers 70-90% discounts, Azure 60-80%, GCP 50-80%. For a training job that would cost $10,000 on-demand, spot instances with 15% checkpoint overhead still yield $6,000-$8,000 in net savings.
Training workloads are inherently interruptible since frameworks support checkpointing. Budget 10-15% overhead for checkpoint storage to S3 or Blob Storage and resume logic, and you still achieve massive savings compared to on-demand pricing with per-second billing on some providers.
But spot interruptions and automatic restarts destroy the ‘instance uptime vs active compute time’ metric that traditional FinOps teams use to measure utilization. An instance that runs 100 hours, gets interrupted 5 times, restarts each time, and delivers 95 hours of productive training shows low uptime utilization even though every paid second delivered value.
The cheapest GPU-hour is the one you stop paying for. Bin-packing workloads onto fewer instances, autoscaling to zero between jobs, and honest capacity reviews against FOMO reservations made during the 2024-25 crunch beat optimizing utilization of over-provisioned on-demand fleets.
Organizations achieving 40-60% cost reduction through mature AI FinOps practices are simultaneously increasing AI workload volume. They’re not rationing compute. They’re eliminating waste hours—the time between job completion and instance termination, the overnight idling of development environments, the reserved capacity sitting empty because teams over-provisioned during scarcity.
Spot instances force a shift from ‘utilization percentage’ to ‘waste hours eliminated’ as the core KPI. That shift breaks compatibility with every FinOps dashboard built for steady-state VM management.
Real-time token tracking answers the only question finance actually cares about
Finance doesn’t care about GPU utilization percentages or DCGM metrics. They care whether the AI product makes money. That requires cost-per-token, cost-per-request, and cost-per-completed-task tracking joined to business outcomes, not infrastructure dashboards showing green bars.
The critical FinOps questions are ‘cost per completed task for the top three AI workflows’ and ‘is cost trending with usage or with waste,’ not raw utilization numbers. Finance needs to know: does our summarization feature cost $0.02 per document or $0.20? Is that cost growing because we’re summarizing more documents or because we’re wasting tokens on poorly-tuned prompts?
Per-token tracking requires a reverse proxy—LiteLLM or Kong—in front of shared vLLM endpoints to inject `x-team-id` and `x-project-id` headers. Export token counters to Prometheus using the vLLM metrics endpoint (`/metrics`), then join token counts with GPU cost in Grafana to produce per-team, per-project unit economics.
Self-hosting breaks even against hosted APIs at approximately 10-15 million tokens per day for a given model, but this calculation requires accurate GPU instance cost divided by tokens-per-second throughput in production. You can’t make build-vs-buy decisions without token-level instrumentation that attributes every API call to a specific feature, user tier, and business context.
Token-level optimization—prompt engineering, caching, model selection—can reduce consumption by 30-50%, but only if every request is tagged with calling context to answer ‘how much does our summarization feature cost per user per month.’ Without tagging, you’re optimizing blind.
Organizations that instrument token costs discover their free-tier users consume 80% of inference budget while generating 20% of revenue, or that a single chatbot feature burns more tokens than the entire rest of the product. These insights don’t appear in GPU utilization dashboards. They require joining business telemetry with infrastructure cost at the request level.
Finance doesn’t want another utilization chart. They want unit economics that tie to revenue and margin. Give them cost-per-task, and they’ll stop asking about utilization.
Governance must happen at workload submission, not monthly budget review
By the time a monthly budget review flags GPU overspend, the training run already burned $50,000 and shipped a model to production. Effective AI FinOps requires approval gates and cost estimates before workloads start.
Any GPU instance above $10/hour requires team lead approval with written justification. This creates accountability at the point of provisioning rather than post-hoc chargeback. When an engineer requests an 8×A100 node, they document the expected training duration, convergence criteria, and business value before the job starts.
Cost reviews before workloads move from testing to production catch expensive decisions when they can still be changed, not after the invoice arrives. A staging training run on a single GPU might reveal that convergence will take 200 hours on the production 16-GPU cluster, giving leadership time to decide whether to proceed, optimize the model, or kill the project.
Real-time usage monitoring and spending alerts for all training and inference jobs enable teams to stop or adjust workloads before costs run away. AI costs can escalate within hours. A misconfigured autoscaler can spin up 50 inference instances overnight. A training job with the wrong batch size can run for days without converging. Alerts tied to spending thresholds catch these failures while intervention is still possible.
A FinOps governance structure defining who approves new model training runs, GPU provisioning, and external API usage prevents the ‘start first, ask forgiveness later’ pattern that drives uncontrolled spend. Teams need guardrails for experimentation versus production. Experiments get time-boxed budgets and automatic teardown. Production workloads get reviews and monitoring.
The cost of governance is trivial compared to the cost of undisciplined spending during the 2024-25 GPU crunch, when teams lost finance trust by burning through quarterly budgets in weeks. Organizations that implemented workload-submission governance saw 30-40% cost reduction in days 31-60 of their FinOps maturity journey while simultaneously increasing AI workload volume, because predictable resource allocation is faster than waiting weeks for budget approval.
Monthly reviews catch problems too late. Workload-submission gates catch them when decisions still matter.
The counterargument: cost controls will kill innovation velocity
Spot instances and aggressive cost controls will slow down AI innovation and model iteration speed, costing the business more in lost competitive advantage than the savings generate in reduced cloud bills—especially when GPU capacity is already scarce.
This argument conflates waste with velocity. Spot instances with checkpointing save 70-90% on training costs while adding only 10-15% overhead for checkpoint storage and resume logic, meaning net savings of 60-80% with minimal impact on time-to-convergence. Checkpointing every 30-60 minutes is a solved problem in modern training frameworks. The overhead is real but marginal.
The real velocity killer is teams waiting weeks for budget approval or GPU capacity because finance lost trust after undisciplined spending during the 2024-25 crunch. When finance doesn’t trust engineering’s cost estimates, every new experiment triggers a budget negotiation. When engineering can’t produce unit economics, finance defaults to rationing.
Governance at workload submission—requiring justification for instances above $10/hour—and real-time cost visibility actually accelerate iteration by making resource allocation predictable and defensible, not by rationing compute. Teams with mature FinOps practices get faster access to GPUs because their spend is defensible and their cost projections are credible.
The organizations achieving 40-60% cost reduction through mature AI FinOps practices are simultaneously increasing AI workload volume, according to documented maturity-stage progressions. They’re not doing less AI. They’re doing more AI with less waste. Waste elimination and innovation velocity are complementary, not competitive.
Consider the alternative: unlimited on-demand GPU access with no governance. Every team hoards capacity. Utilization stays at 5%. Finance sees runaway spend with no business justification and imposes hard budget caps mid-quarter. Now no one can provision new resources. Innovation stops.
Cost controls done right increase velocity by building trust between finance and engineering. Cost controls done wrong ration compute arbitrarily. The difference is whether you measure cost-per-task or just total spend.
Traditional FinOps dies where AI workloads begin
Traditional FinOps dies where AI workloads begin—not because the principles are wrong, but because the assumptions don’t survive contact with training runs that reset baselines, inference loads that oscillate to zero, and spot instances that save 80% while tanking uptime metrics.
The assumptions were: steady utilization, annual budgets, single allocation models, monthly reviews. AI workloads offer: bimodal demand that swings from 0% to 100% within minutes, cost baselines that reset with every model deployment, four simultaneous allocation models required for complete chargeback, and costs that escalate within hours if unchecked.
The path forward isn’t better dashboards showing 5% utilization in red. It’s shifting the entire practice from allocation-based accounting to waste elimination, from utilization percentages to cost-per-task, and from monthly budget reviews to workload-submission governance.
Finance gets unit economics that tie to business outcomes—cost per completed task, cost per user, cost per feature—not infrastructure metrics that don’t translate to revenue or margin. Engineers get faster access to GPUs because spend is defensible and projections are credible, not because they’re gaming allocation formulas.
And that 5% utilization number stops being an embarrassment and starts being evidence you’re not paying for idle capacity between jobs. Mature AI FinOps practices measure waste hours eliminated, not utilization percentage optimized. The goal isn’t 60% average utilization. The goal is zero hours paid for but not used.
The technology stack exists: DCGM Exporter for GPU metrics, Prometheus with team and project labels, Grafana for visualization, reverse proxies for per-token tracking, spot instances with checkpointing for 70-90% savings, governance gates at workload submission. The formulas exist: `team_cost = (namespace_gpu_seconds / total_gpu_seconds) × cluster_monthly_cost` for namespace allocation, per-token costs from joining vLLM metrics with GPU hourly rates, self-hosting breakeven at 10-15 million tokens per day.
What doesn’t exist yet in most organizations is the willingness to admit that traditional FinOps assumptions break under AI workloads and the commitment to rebuild the practice from GPU seconds up.
The question isn’t whether to do FinOps for AI. The question is whether you’re ready to rebuild the practice from first principles, starting with the acknowledgment that 5% utilization isn’t the problem—it’s the clue that you’re measuring the wrong thing.